SerpApi's Extract API Wants to Kill Your Custom Web Scrapers
SerpApi's new Extract API turns any public web page into structured data for AI workflows — and you only pay when extraction succeeds. Here's what it does, what it costs, and who should care.
SerpApi made its name selling developers clean, structured access to search results — the kind of API you reach for when you need Google results without the CAPTCHA roulette. On October 13, the company announced it wants to be much more than that. Its new Extract API pulls structured content from any public web page, and the pitch is simple: stop hand-building scrapers.
A Web Scraping API That Starts From Search
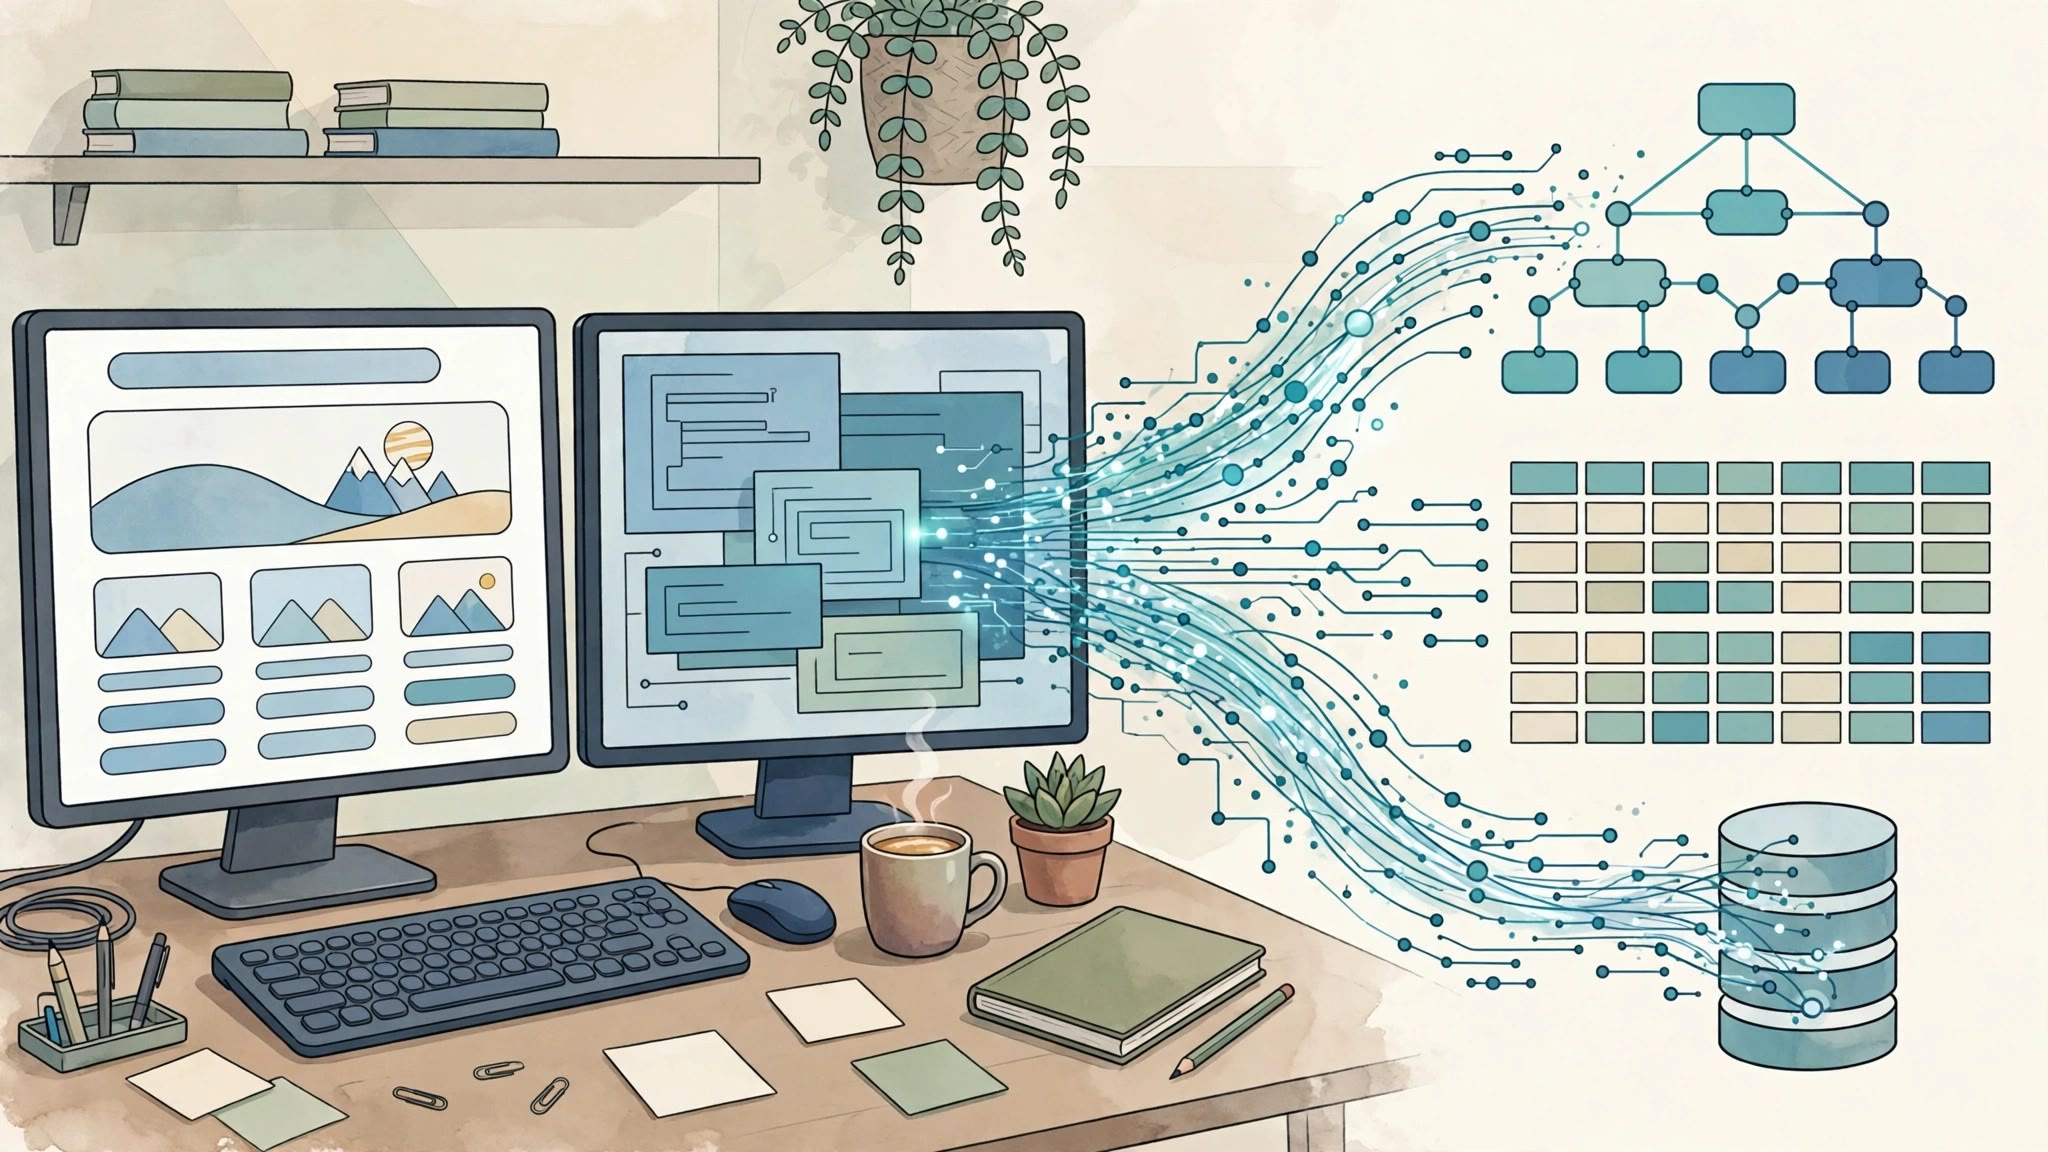
Here's the idea. Today, a typical data pipeline looks like this: query a search API for URLs, crawl each page yourself, then write and maintain parsing code for every site layout you care about. SerpApi's Extract API collapses that into one platform — give it a URL or a bounded site-discovery job, and it returns normalized, developer-ready data.
The target workloads are very 2026: AI agents that need page content plus evidence, research platforms, market monitoring, SEO and content discovery, and RAG knowledge enrichment. That last one is telling — retrieval-augmented generation lives or dies on the quality of the documents you feed it, and a reliable extraction layer is exactly the unglamorous infrastructure RAG pipelines keep reinventing.
The announcement came via PR Newswire out of Austin, Texas, and the API is live across all SerpApi accounts already. No waitlist, no staged rollout — which suggests the company has been dogfooding this with existing customers for a while.
The Problem It's Actually Solving
Anyone who has maintained a scraper knows the real cost isn't writing it — it's keeping it alive. Sites change their markup without warning, anti-bot systems evolve weekly, and every new source means another bespoke parser to babysit. For teams feeding AI workflows, this maintenance tax is brutal: your AI tool stack is only as reliable as the jankiest scraper in the chain.
SerpApi's bet is that extraction, like search before it, is a commodity problem best solved once and sold as infrastructure. The company has been in the structured-data business since 2017 — founder and CEO Julien Khaleghy has grown it to 100-plus specialized APIs — so this isn't a pivot so much as a natural expansion of the territory it already owns.
How It Works and What It Costs
The pricing model is the most developer-friendly part: you're billed per successfully extracted page. Failed extractions cost nothing, which removes the worst part of scraper economics — paying for requests that return garbage.
There are honest caveats in the fine print. The parser is generalized, so support varies by site; URLs from engines SerpApi already covers deeply — Google, Bing, YouTube — get specialized schemas with richer fields. That's a reasonable tradeoff, but it means you should test Extract against your actual target sites before committing a pipeline to it. A generalized extractor will never match a hand-tuned parser on a weird single-page app, and SerpApi isn't pretending otherwise.
Who Should Actually Use This
Extract makes the most sense for three groups. First, teams building AI agents that need to cite real page content — grounding agent output in extracted evidence is becoming table stakes. Second, market-intelligence and research shops that track dozens or hundreds of sources and are tired of maintaining the plumbing. Third, anyone enriching a RAG knowledge base, where clean, structured documents beat raw HTML dumps every time.
Who shouldn't bother? If you scrape exactly one stable site and your parser hasn't broken in a year, keep it. If your targets are heavily bot-protected or require logins, a general extraction API won't save you. But for the large middle of the market — many sources, moderate complexity, zero desire to maintain scrapers — this is the kind of boring infrastructure win that quietly saves engineering months. The best developer tools are the ones that delete work, and Extract is aimed squarely at deleting yours.